
Saving Costs on Sentry

If your Sentry bill is getting too high, there are three ways to bring it down. Only two of them involve leaving Sentry:
- Send fewer events to Sentry. Filter errors you do not want, or sample error events.
- Use Bugsink. Keep sending the errors; we run the Error Tracker for you at a lower price.
- Self-Host Bugsink. Keep sending the errors and run the Error Tracker on your own infrastructure.
The first option changes what you collect. The other two change where you send it.
Why Sentry gets expensive
Sentry counts error occurrences, not just issues. A single bug in a loop may still appear as one issue in the UI, but every occurrence counts towards your volume.
The current Team plan starts at $26 per month with annual billing and includes 50K errors. At larger volumes, its published pay-as-you-go rates put 3 million errors at about $600 per month and 50 million at about $6,441 per month. Monthly billing costs more.
Whether that is expensive depends on what you use Sentry for. It is a broad observability platform; if you use that whole platform, the price may be perfectly reasonable. If you mainly use it for Error Tracking, there are cheaper ways to do that job.
Send fewer events to Sentry
This is the least disruptive place to start: keep Sentry, but send less to it.
Filter known noise
Some errors really are noise. You can drop them before they leave the application; many Sentry SDKs have a callback such
as before_send for this. The arithmetic is simple: if one noisy exception accounts for 30% of your events, filtering
it reduces your error volume by 30%.
Of course, that filter is now something you have to maintain. If it catches too much, it can also hide an error you did want to see.
Sample error events
Sampling is blunter: send a percentage of all error events. At a 10% sample rate, roughly one in ten events reaches Sentry; at 1%, roughly one in a hundred does.
You keep stacktraces and examples of common errors, but the occurrence counts become estimates. Rare errors and rare variations are easier to miss. That may be fine when each new event tells you very little.
Ignore whole categories
You can also exclude whole classes of non-actionable errors: scanners hitting nonsense URLs, expected client disconnects, or a known-bad integration endpoint. This can remove a lot of volume at once.
The same warning applies: somebody has to maintain that list. The category may stop being harmless; the filter won’t know that.
Shouldn’t you just fix the errors?
Well, yes. Fewer errors are good – not because they make your Error Tracker cheaper, but because they mean your software is more stable.
Unfortunately, error volumes tend to be highest at exactly the wrong time: after a broken deploy, during an external outage, or while a dependency is failing in a loop. Lots of information is good during a crisis. That’s when you need it most.
Filtering, sampling, or muting a known error may still be exactly what you want. The point is that cost should not force the choice between a big bill and missing data. If the events are useful, you can change the Error Tracking backend instead.
Alternatively: Use Bugsink
If your application already sends errors to Sentry, trying Bugsink can be just a DSN change. Bugsink uses the same Sentry SDKs, so there is no new integration to build. New events go to Bugsink; historical events stay where they are.
Sign up and we run Bugsink for you. We handle the servers, TLS certificates, upgrades, storage, backups, and outgoing email. You keep using the same SDKs and keep sending the errors that help you debug.
Here are the actual numbers. Bugsink is cheaper at every paid level shown below. Prices are monthly and in US dollars. The Sentry estimates use the $26 annual-billing Team base, its included 50K errors, and its published pay-as-you-go rates.
| Monthly errors | Bugsink | Sentry Team |
|---|---|---|
| Around 100K | 75K for $16 | 100K for about $44 |
| Around 500K | 600K for $50 | 500K for about $132 |
| 3 million | $158 | about $600 |
| 50 million | $1,288 | about $6,441 |
Sentry does more, of course. This table compares Error Tracking only. The pricing page has all Bugsink plans; the managed page explains what we take care of.
Or Self-Host Bugsink
The third option is to run Bugsink on your own infrastructure. There is no Bugsink subscription and no vendor intake quota. You pay for the infrastructure, and you spend your own time operating it.
Depending on your setup, this can be the cheapest option at high volumes. One Bugsink customer handles more than one million errors per day on Google Cloud Platform for less than $100 per month.
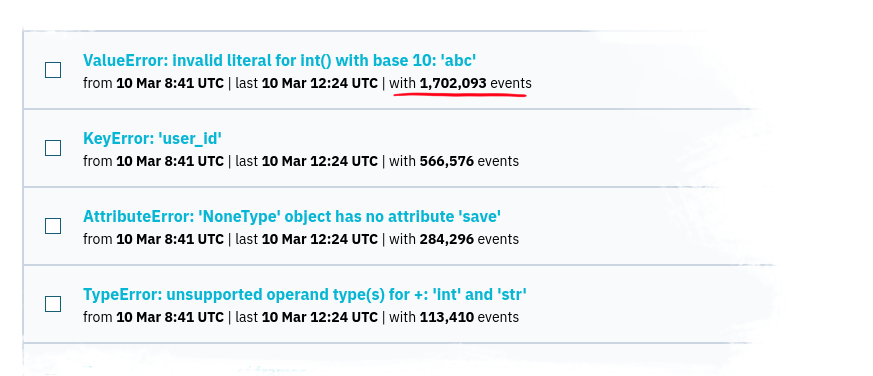
Our own benchmark sustained 1.5 million events per day on a $5 VPS with 2 vCPUs and 4 GB RAM. That is a benchmark, not a production recommendation. If you’re saving literal thousands per month, there is no need to fly so close to the sun: pick something with a bit of margin.
The same efficiency also makes the managed prices above possible. The scalability page has the full benchmark and its limits.
Just because you can…
The goal of Bugsink is to help you fix your bugs. Which means that we’ve done a good job when you have as few errors as possible, and a bad one when you scale up to its capacity.
So what’s the point of all this scalability? Think of it as a safety net: you don’t want to have to worry about your Error Tracker when you’re dealing with a crisis. Or ever, really.
Back-of-the-envelope
Perhaps somewhat surprisingly, the biggest infrastructure consideration at this scale is storage. At 1.5 million events per day, you’re dealing with about 46 million events per month. At 50 KB per event – an average I’ve personally observed for Python setups – keeping all of them would require about 2.3 TB per month.
Check the actual event sizes for your application and calculate accordingly. Is 2.3 TB what you want or need? Maybe.
Bugsink lets you choose a storage cap for each project. Smart retention keeps representative events from each issue and throws out increasingly repetitive ones. You can work that cap back to an approximate number of days, but note that retention is not linear. At all.
In practice, start with a rough average event size and daily volume, with some margin on both. Look at the disk sizes available to you, leave some room for the OS and logs, and pick a disk size at a cost that works for you. Then work backwards to a retention cap.
Self-Hosting still means looking after a production service: upgrades, TLS, backups, storage, and outgoing email become your responsibility. Bugsink keeps the moving parts small – SQLite works by default and one container is enough – but your time is not free. The Self-Hosted overview and installation guide cover the practical details.
What changes when you leave Sentry
Bugsink is not a feature-for-feature replacement for Sentry. It focuses on Error Tracking. There is no performance tracing, session replay, profiling, or wider observability platform. If you want those things, Bugsink does not replace them. Tracking errors first is a deliberate product choice, not a claim that nobody needs APM.
Bugsink is complete within Error Tracking. It groups errors into issues and gives you stacktraces, local variables, request data, tags, search, alerts, source maps, and the context around each failure. It accepts events from the Sentry SDKs. It does not migrate your old Sentry history.
Conclusion
If filtering or sampling removes data you do not want, do that. It is the smallest change and can cut a Sentry bill by a lot.
If you do want the data, and the price of sending it to Sentry is the problem, change the backend instead. You can sign up for free and let us run Bugsink for you, or Self-Host Bugsink on your own infrastructure.